---
title: World model
description: "The living picture an agent keeps of the world it works in: what's true, how sure it is, and what to do next."
---
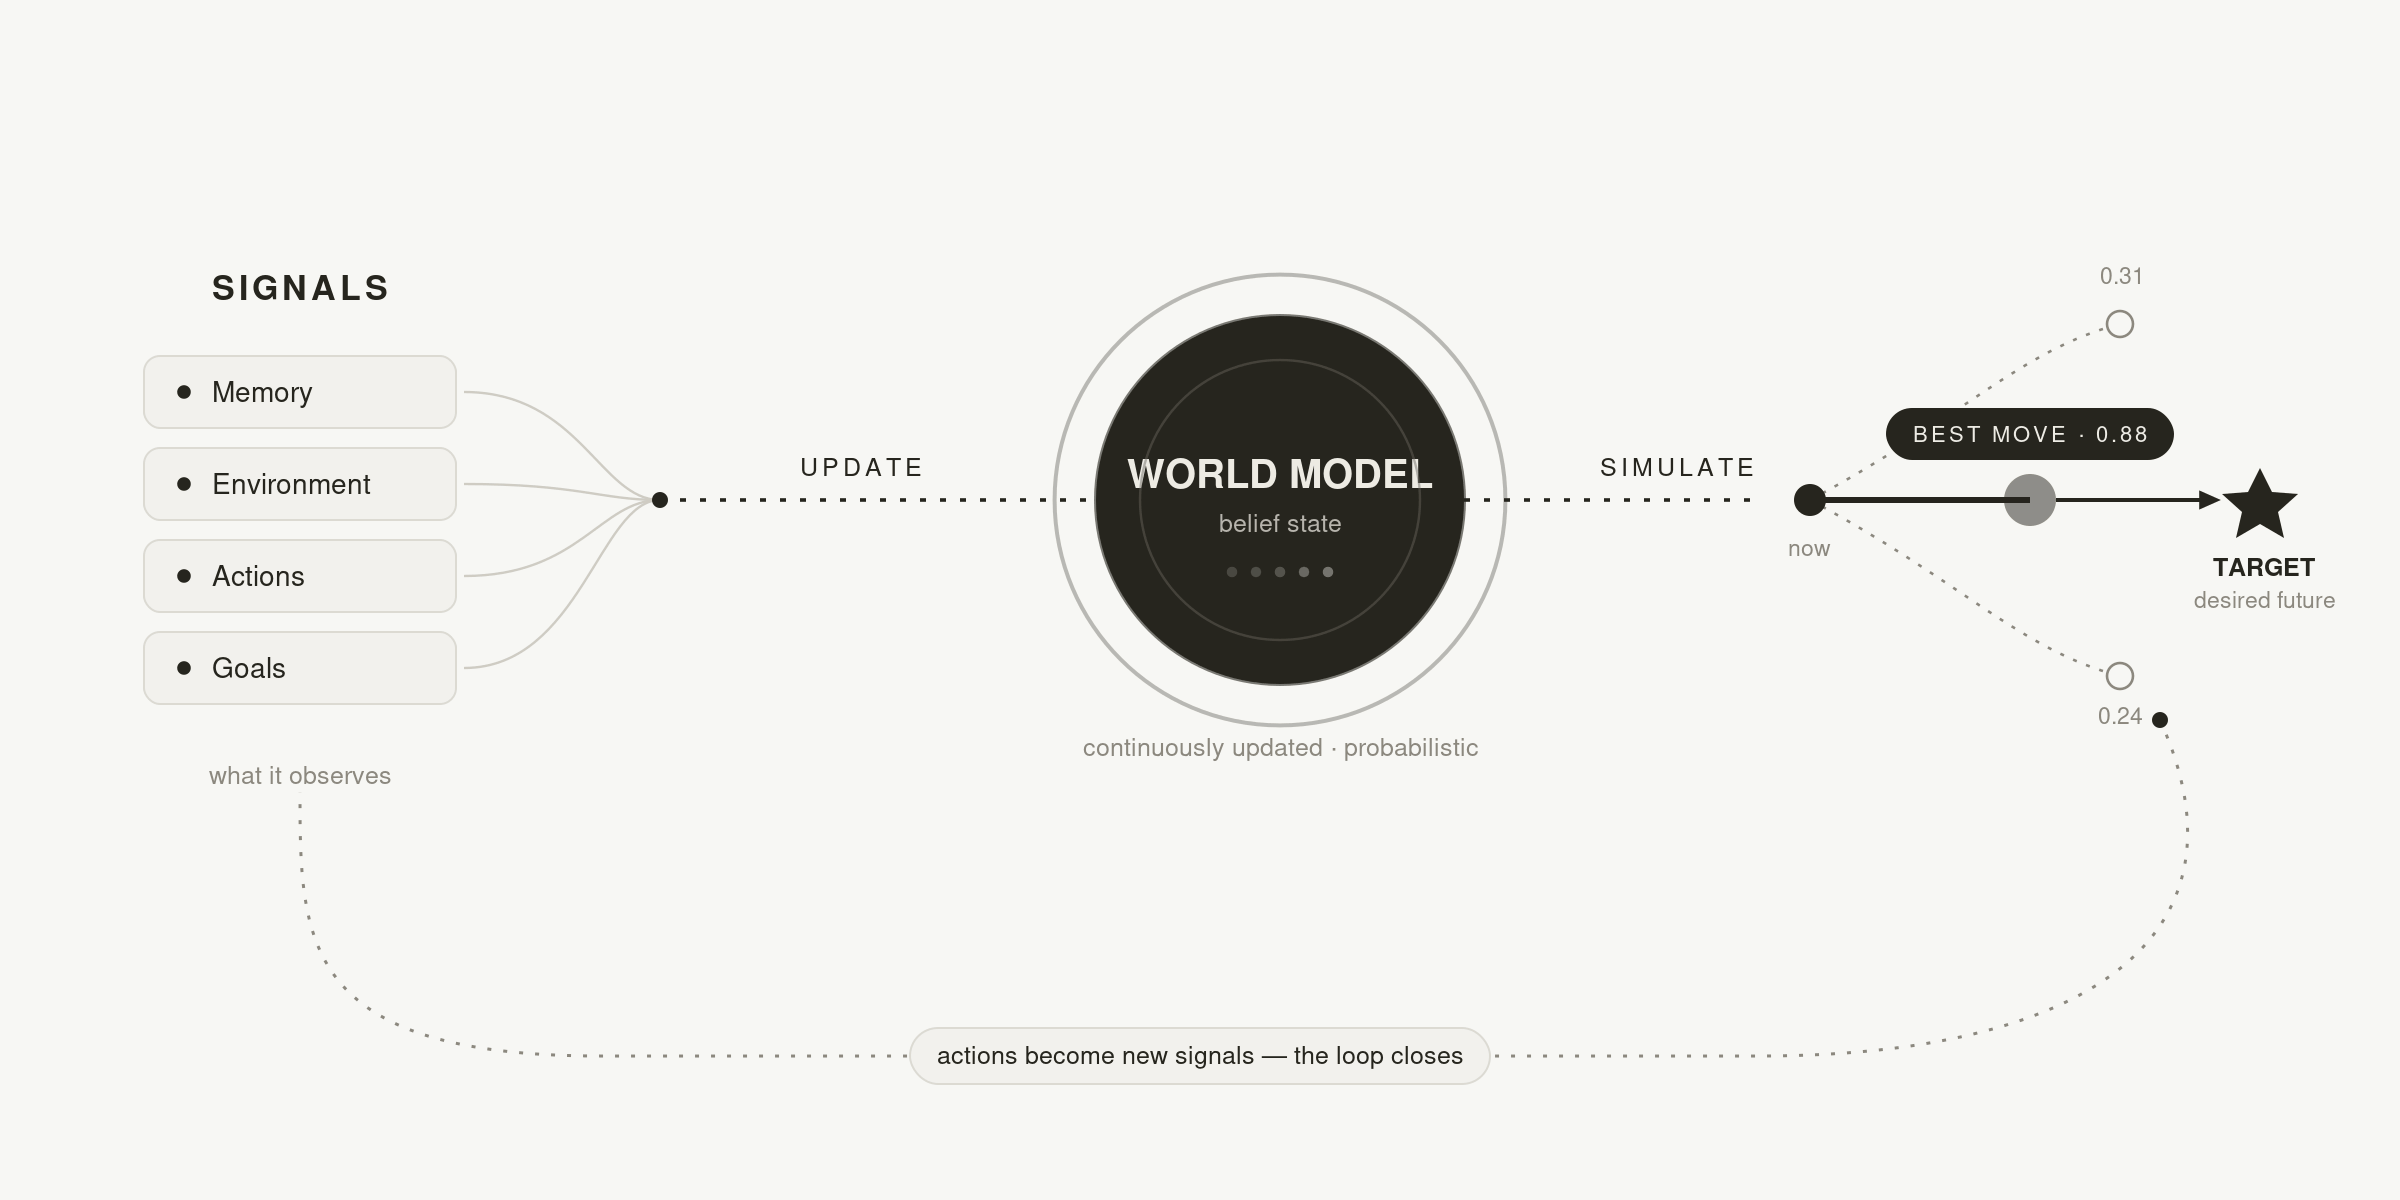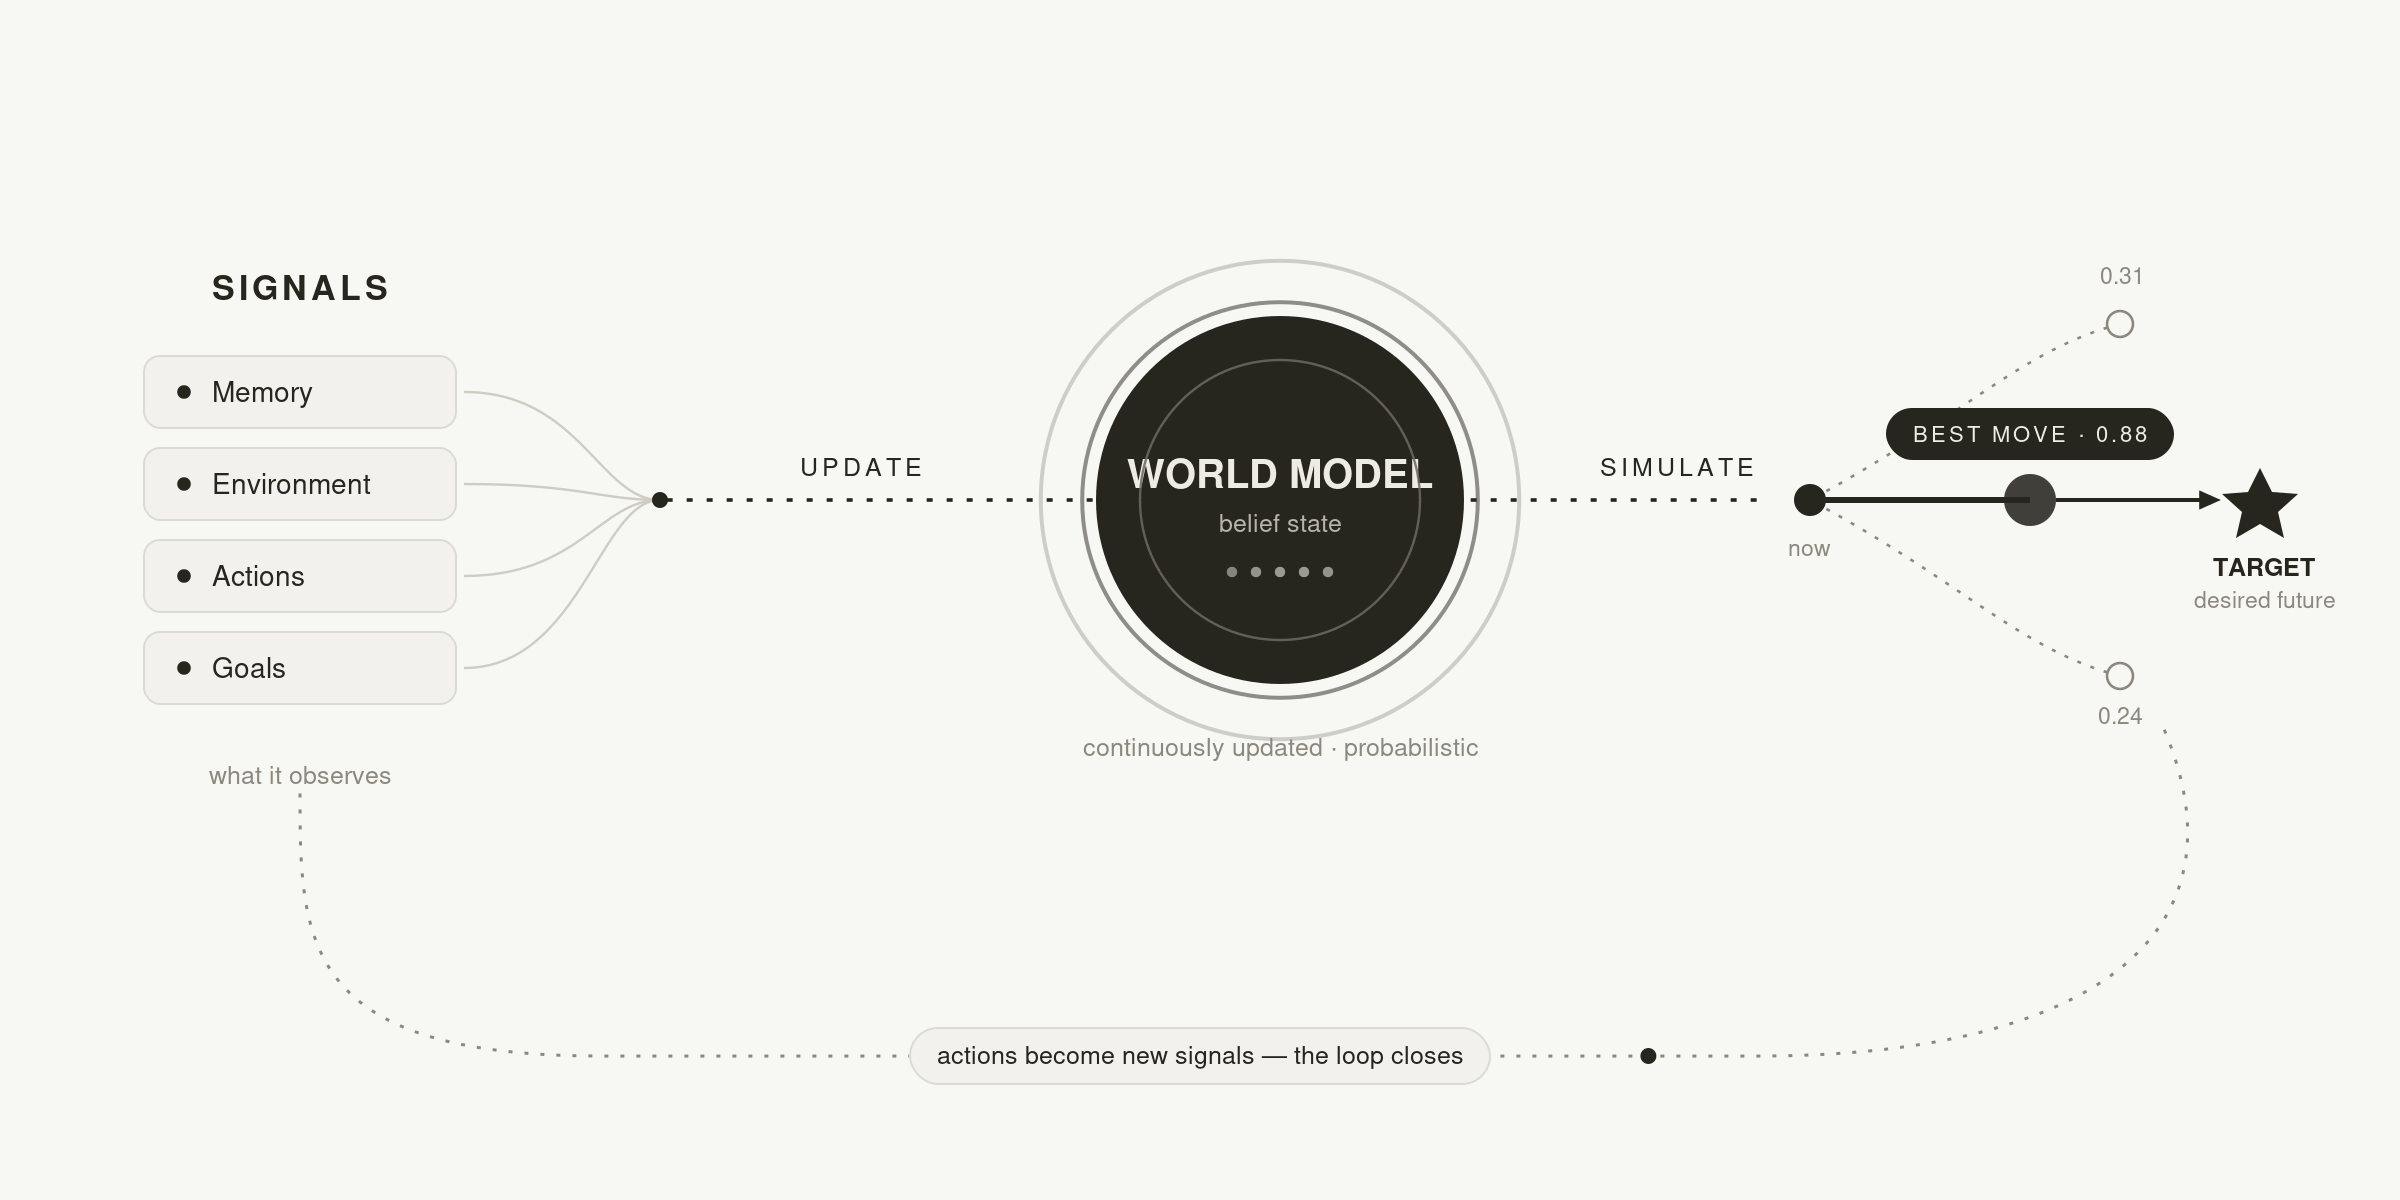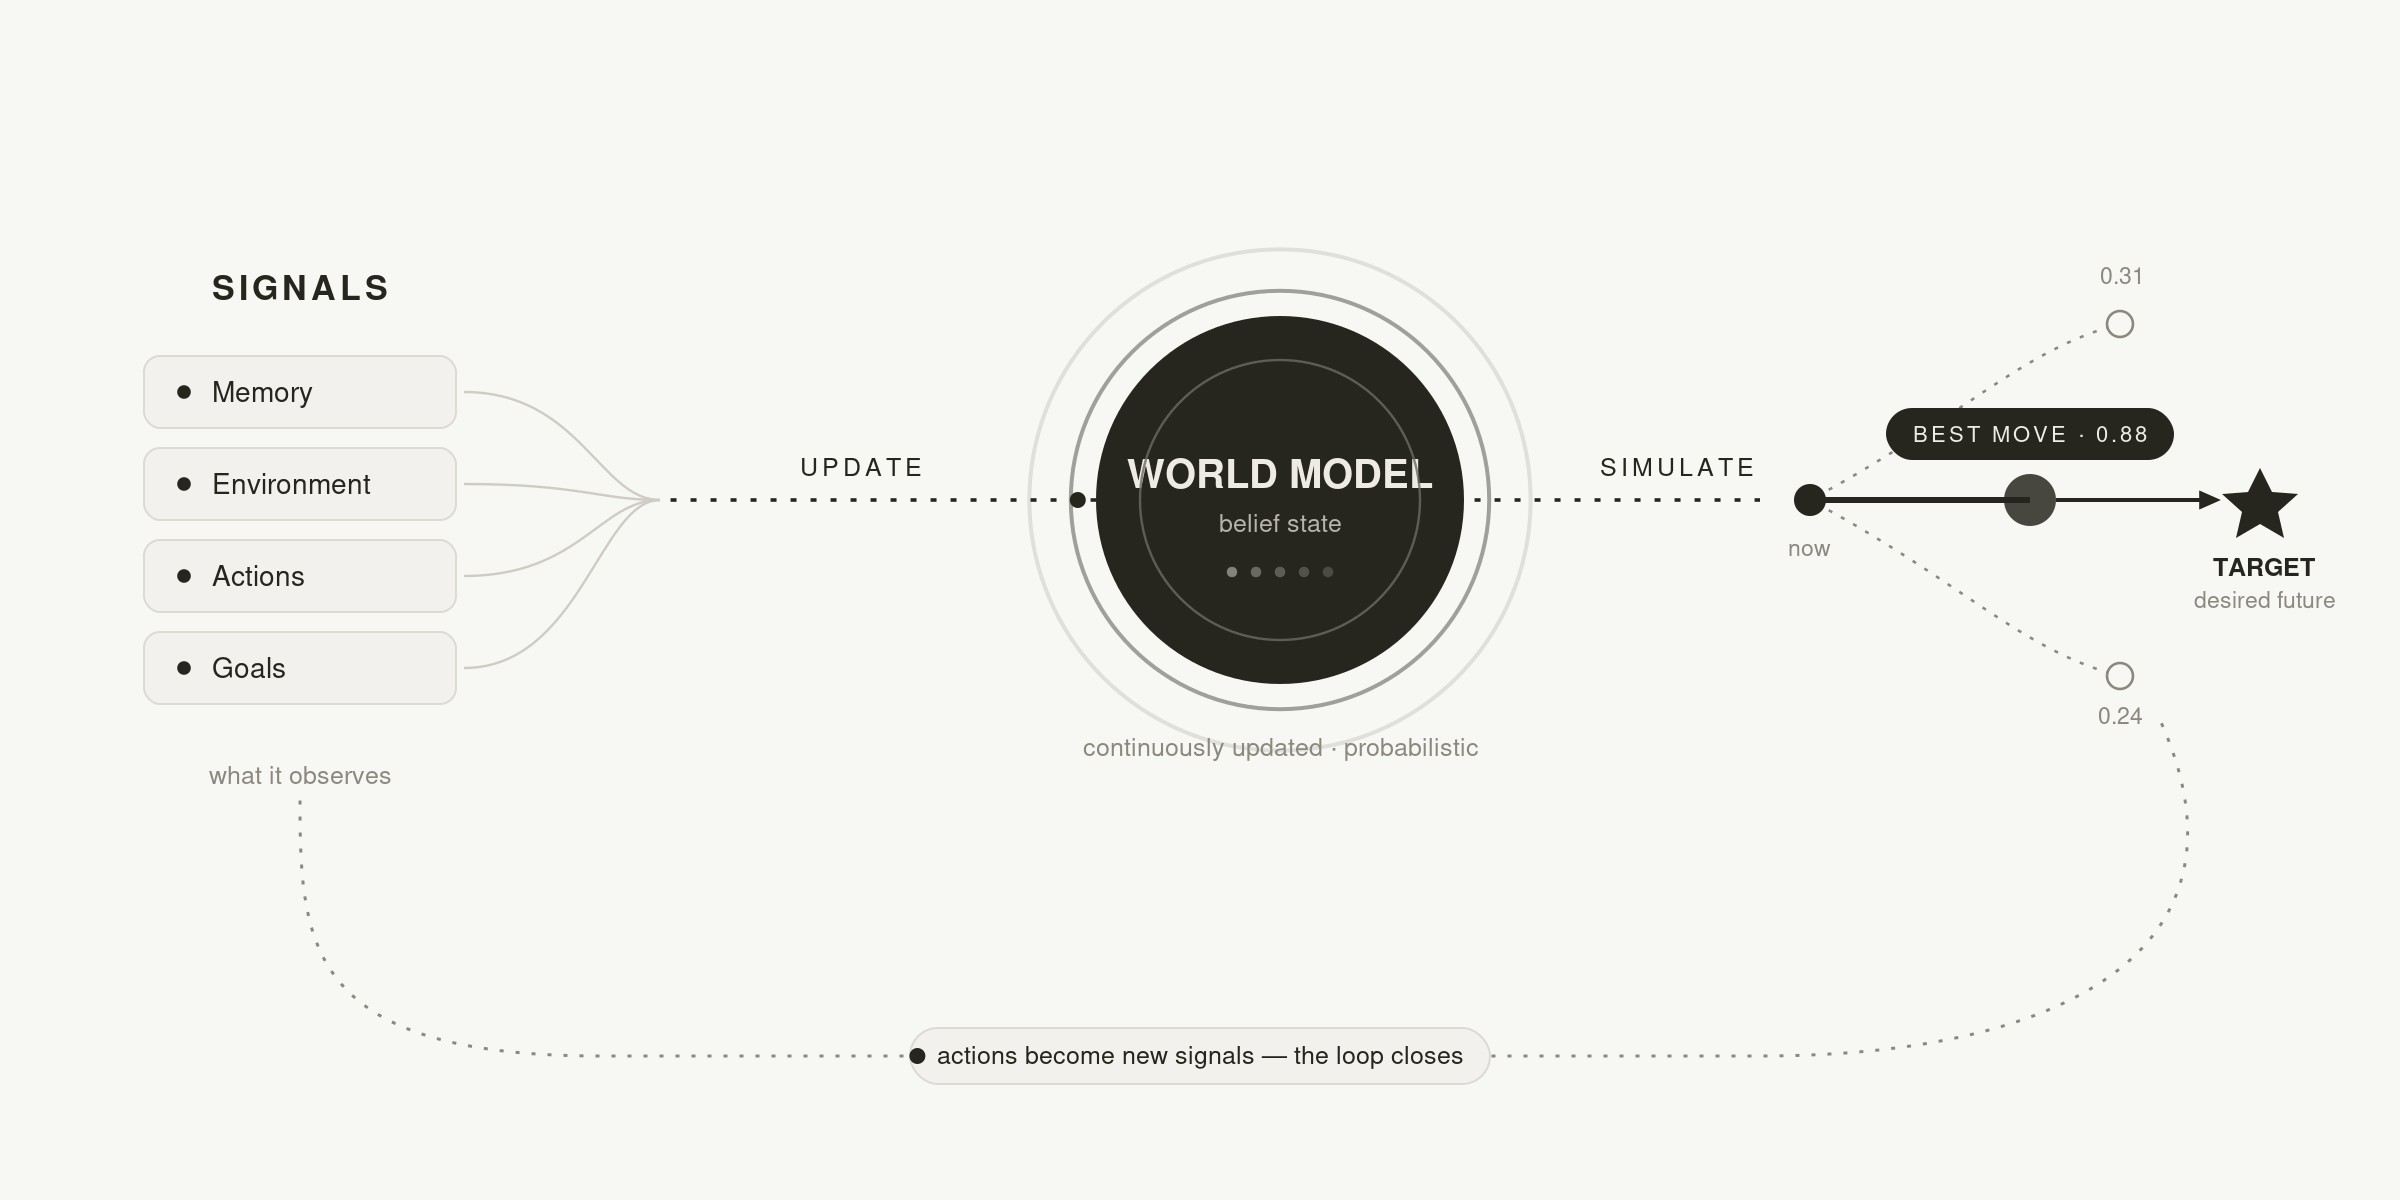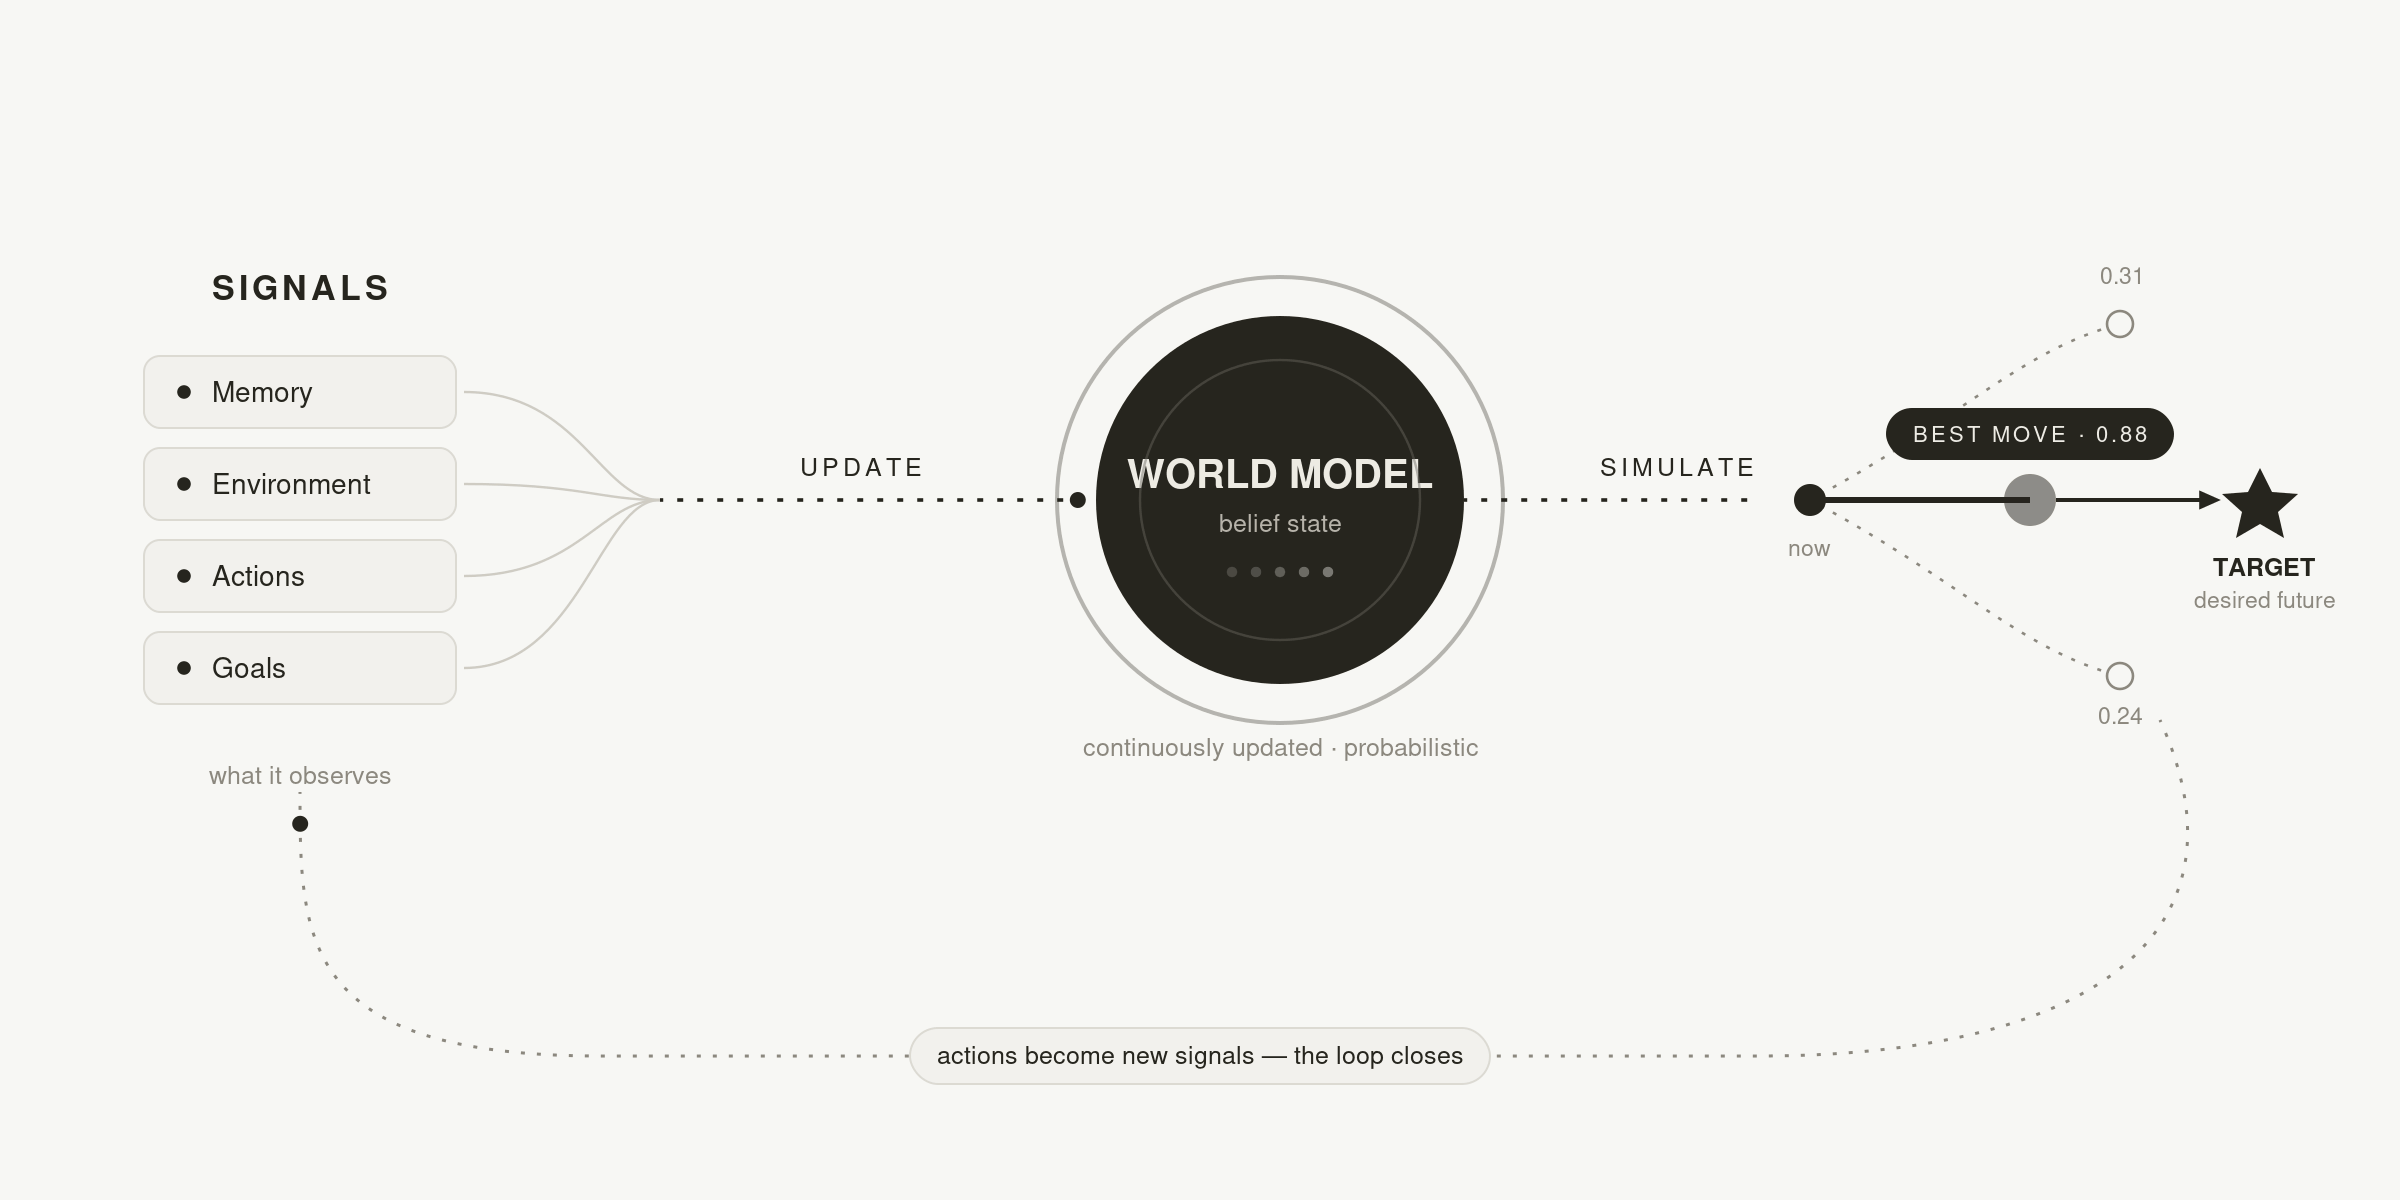
**A world model is the picture an agent acts from.** It is a living, structured representation of the world an agent works in: what is true right now, how sure the agent can be, what it is steering toward, what rules bind it, and what it can do next. The agent reads this picture before every move and updates it after, so each turn starts from what is actually true instead of from scratch.
That is what separates a world model from a store of facts. A store answers what was said. A world model answers what is true, how confident the agent is, what would change its mind, what it can do about it, and what happens when it does. Build a memory system to act on rather than to retrieve from, and this is the shape it takes.
 This page names the frame. Every page under it owns one part.
## The six parts you touch
A world model has six parts a developer works with directly, plus a seventh the engine assembles from them. Each part answers a different question the agent asks before it acts:
- **[Environment](/dev/core/environment).** *Where am I?* The world the agent operates on: a codebase, an account, a production line, a portfolio, a patient. The ground truth, plus the entities and relations that structure it.
- **[Observations](/dev/core/observations).** *What just happened?* The input boundary. Everything the agent sees streams in as observations: tool results, files, messages, sensor readings, filings. This is the only way anything enters.
- **[Belief state](/dev/core/beliefs).** *What's true, and how sure am I?* A graph of explicit posteriors over the environment, not an opaque latent vector. Each belief carries confidence, evidence, and provenance. Where a claim resolves against a real outcome, that confidence is calibrated against history (events labeled high resolve true at roughly that rate; see [Contracts](/dev/internals/contracts)). Where there's no outcome to resolve against, confidence reflects the balance of evidence, not a frequency. It spans three tenses:
- **Past:** what's been observed, what evidence has arrived (the ledger).
- **Present:** what's currently held true, with confidence and provenance (the active claim set).
- **Future:** what action would move the world model closer to reality (the next moves, ranked).
- **[Intent](/dev/core/intent).** *What am I after?* The goals and success criteria the current decision is measured against, plus the gaps still open.
- **[Policy](/dev/core/policy).** *What must I respect here?* The rules of this world: invariants that must always hold, which sources outrank which when they disagree, the conventions of the place, and the anti-patterns to avoid. This is a modeling lens you encode today, not a constraint the engine enforces.
- **[Actions](/dev/core/actions).** *What can I do?* The set of moves available in this world, each with a safety class (read-only, mutating, or needs-approval).
The seventh thing is the **[worldview](/dev/core/worldview)**: the bounded projection of all six, scoped to the one move the agent is about to make. The agent reads the worldview, not the whole frame.
Inside the belief state, beliefs are the unit of account, edges record how they relate, gaps are the open questions, and contradictions are where the state disagrees with itself or with new evidence. [Moves](/dev/core/moves) rank what action would close those gaps fastest; [clarity](/dev/core/clarity) scores how ready the picture is to act on. How edges are typed and how contradictions weight by downstream dependency are [Belief state](/dev/core/beliefs)'s to explain; this page just locates them in the frame.
## You declare the world, the engine runs it
The split is clean. The environment, the action set, the policy, and the intents are things you encode for a domain. You name the entities and relations that matter in a codebase, lay out the actions an agent may take on an account, write down the invariants a portfolio must respect, and state the goals it is steering toward. That declaration is your world.
The engine takes it from there. It maintains the belief state as observations arrive (extract, fuse, decay) and projects the worldview from that state plus your declaration. You do not hand-maintain confidences or relationships. You observe, and the posterior moves.
Today, policy and the action set are how you *model* a world: a declarative surface you encode and your agent reasons over. The engine surfaces them in the worldview and tracks which actions a constraint would flag, but it does not itself gate execution. A declarative config surface that the engine enforces is on the roadmap. Until then, treat policy and actions as the structure your agent reads, not a guardrail the runtime imposes.
## The agent reads a worldview, not everything
The agent never loads the whole frame at once. As a corpus grows, that would put a thousand items in front of a model that does its best work on a handful. Instead it reads a **[worldview](/dev/core/worldview)**: a decision-sized projection scoped to the move at hand. The worldview keeps what bears on the current decision and drops the rest, capped to a small working set and ranked by value to that decision.
Then the agent acts. The action folds back in as the next observation, the belief state updates, and the next turn projects a fresh worldview. That is the loop: observe, believe, act, with each action becoming the next thing observed.
```
observe ──► believe ──► act
▲ │
└─────────────────────┘
the action becomes the next observation
```
## The read side of the loop
`beliefs.read()` returns the world model in full: the agent's beliefs, the relationships between them (what supports, contradicts, derives), all open gaps, active contradictions, the clarity score, the ranked next moves, and the serialized prompt.
```ts
const world = await beliefs.read()
world.beliefs // all beliefs the agent holds
world.goals // what the agent is pursuing
world.gaps // unknowns and open questions
world.edges // relationships: supports, contradicts, derives
world.contradictions // active conflicts that need resolution
world.clarity // 0-1 readiness score
world.moves // suggested next actions
world.prompt // serialized context for LLM injection
```
`read()` is the full picture. For a single turn you want the slice, not the picture, and `before(query)` loads it: the decision-sized worldview for the query at hand, with the top move riding back as `context.moves[0]`.
```ts
const context = await beliefs.before(userMessage)
const result = await myAgent.run({
systemPrompt: context.prompt,
message: userMessage,
})
```
When the turn produces output, `after(text)` folds it back into the state, closing the loop. The action becomes the next observation, and the world model gets sharper at predicting its own effects over time.
```ts
await beliefs.after(result.text, { tool: 'edit_file' })
```
The engine ranks the single next move today, and can project a move's value several steps forward once a world has enough action-to-outcome history. That forecasting layer is honest about its evidence and stays low-confidence until the history is real. [Moves](/dev/core/moves) covers it in full.
## One world model, every agent's contributions
When several agents work the same world, the world model is the fused view: one picture assembled from every agent's contributions. Each agent writes under its own `agent` identifier, and the backend merges those writes into a single shared posterior. The merge is order-independent, so the same set of contributions lands on the same posterior no matter who wrote first. Order shapes the audit trail of who saw what and when; it never moves the answer.
To share one fused world model, every contributing agent uses the same `namespace` (the logical problem space) and `writeScope: 'space'`, so writes land in the common store rather than per-agent or per-thread. With a single agent, the world model is just that agent's belief state. Why the merge is order-independent, and the byte-equal test and CI calibration gate that hold it there, are covered in [Belief state](/dev/core/beliefs); the namespace and scope rules are in [Scopes](/dev/sdk/scoping).
## The section map
This page is the overview. Each part of the frame has its own page. The six parts above carry the frame; Worldview, Clarity, and Moves are the read-side projections of it, listed on their own here for findability rather than as a seventh, eighth, and ninth part.